How I Manage Multiple AI Coding Agents
How I coordinate AI coding agents with task briefs, Git worktrees, targeted tests, and review gates, including what failed during a real development push.
During a recent development push, my agents attempted to land 43 changes. Fifteen landed.
The rest ran into failed checks, merge conflicts, or infrastructure problems that kept the checks from running. That was useful information, even if it wasn't the number I wanted to see.
I use multiple AI agents to help build and maintain software. They can investigate problems, write code, test changes, and review each other's work. But once several agents are working at the same time, the hard part shifts. I need to know what each agent is responsible for, how its work gets checked, and what happens when its change meets everyone else's.
That's what this workflow is for.
I've written before about building an agent harness with memory and gates. This is a closer look at the software development side: how I work with agents from the initial task through review and release.

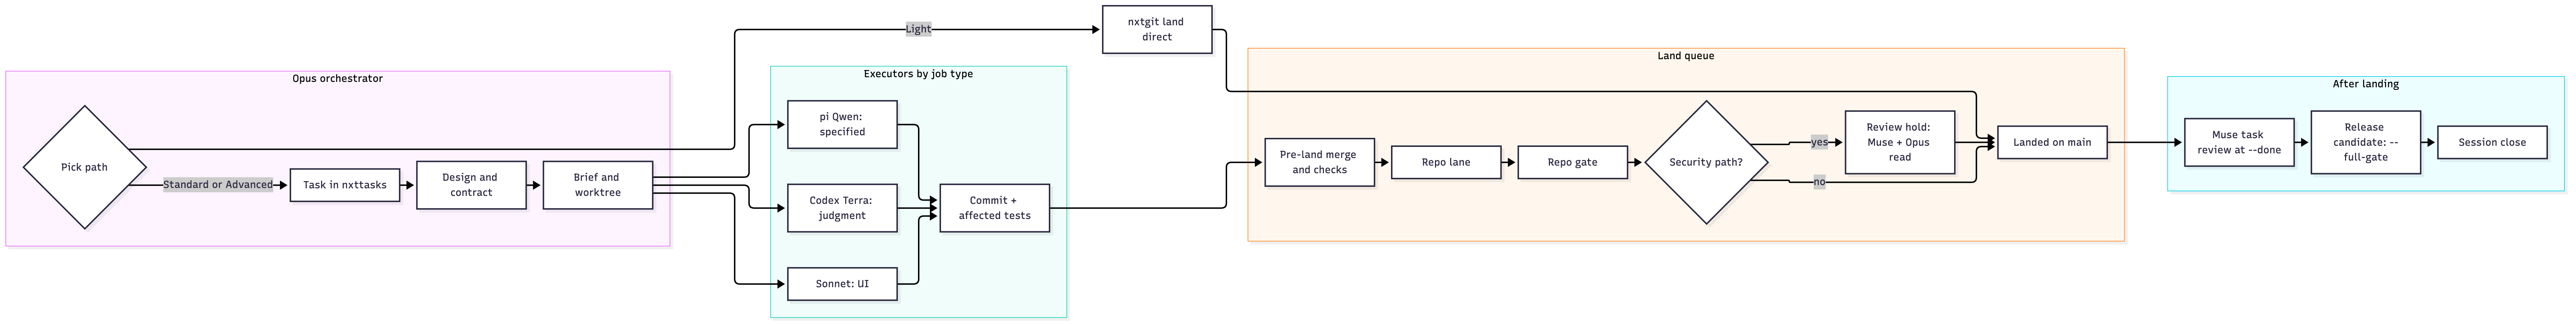
Open the full-size workflow diagram.
I choose the path before assigning the work
The workflow starts with a question: how much process does this change need?
A small, contained change can take a lighter path through the landing process. For larger work, I create a tracked task, work through the design and contract, and prepare a brief for the agent doing the implementation.
The contract describes what needs to stay true. The brief explains the job: the problem, the files involved, the boundaries, and the checks that will show whether the result meets the task.
For example, if an agent is changing how a queue handles failures, "fix the queue" is a poor assignment. A useful brief identifies the failure behavior, the expected result, and the tests that should prove it. The agent can then work within those boundaries instead of making up the missing requirements.
I use an orchestrating agent to help me turn the work into tasks and manage the handoffs. I'm still responsible for setting direction and making the decisions that affect the project.
Different agents take different kinds of work
I don't send every task to the same model. My current setup uses a few lanes based on the kind of judgment the work requires.
For a task I can specify clearly and verify with a test, I use pi with a local Qwen model. That might be a contained implementation where the brief defines the inputs, expected behavior, and acceptance check.
For work that needs more investigation or judgment, I use Codex. A cross-file refactor, a difficult test failure, or a change to Git tooling may need an agent to reason through details that the initial brief can't fully specify.
For interface work, I use Sonnet, including visual review of what was built.
Opus helps orchestrate the work, including planning and attention to security-sensitive changes. A separate review step examines completed task changes.
These assignments are a snapshot of what I'm using now. Models change, and so does the work. The decision I care about is whether the agent can do the job within a clear scope and whether I have a way to check its result.
I described the local side of this setup in more detail in how I built a coding agent that runs on my own machine.
Each implementation agent gets its own worktree
When agents work in parallel, they need room to make changes without stepping on each other.
I use a separate Git worktree for each implementation task. A worktree is another working directory connected to the same repository, with its own branch and files. That lets one agent change a feature while another works on a different task.
The worktree doesn't make the changes compatible by itself. Two agents can still make conflicting assumptions or edit the same part of the system in different branches. What it gives me is a clear boundary: I can see which change belongs to which task, test it, and bring it together with the rest of the project deliberately.
The brief and the worktree travel together. The agent gets a defined job and a defined place to do it.
The agent runs affected tests before the change enters the queue
When an agent finishes its implementation, it commits the change and runs the tests affected by its work. That gives it a chance to catch problems while the task and its context are still fresh.
From there, the change enters a landing queue. "Landing" is the step where the work is brought onto the main branch.
The queue checks the change against the current state of the repository and runs the appropriate repository gate. If the gate fails, the failure goes back for another pass. If the check couldn't run because of an infrastructure problem, that's treated differently from a test that ran and failed.
That distinction matters. An agent shouldn't rewrite working code because a machine ran out of disk space. It also shouldn't declare a change finished because the test runner never started.
I've written more about the general idea of giving agents acceptance tests. In this workflow, those tests are part of the handoff between the agent that builds a change and the system that brings it into the repository.
Security-sensitive changes get another look
A passing test is evidence, but it isn't a complete explanation of a change.
Some paths deserve more scrutiny because the consequences of a mistake are different. In my workflow, changes involving authentication, guardrails, Git handling, terminals, dependencies, or lockfiles get an additional review of the relevant changes.
The workflow also includes a task review when the work is completed. Before a release candidate, the full gate runs.
I don't read every line produced by every agent. I do want the review process to be explicit about where additional judgment is needed and what happens when it finds a problem. The goal is to give the agents enough freedom to work while keeping a route for findings to go back to the right task.
What the first numbers showed me
The 43 landing attempts I mentioned at the start came from a development push on November 16 and 17. Of those attempts:
- 15 landed
- 13 encountered gate failures
- 7 encountered conflicts
- 6 could not run
Those are counts of landing attempts, not a success rate for individual agents or a measure of code quality. They show where work stopped in that push.
The same push included 57 local pi launches, nine of which were reported dirty. In practical terms, that meant the worktree still had changes left when the job stopped and needed attention before it could move forward.
Those numbers gave me places to investigate. A gate failure might point to the change, a test, or an assumption in the brief. A conflict points to how parallel work meets again. A gate that can't run points to the infrastructure around the work.
The diagram shows the process I'm building around those handoffs. It doesn't mean the process is finished or that every run moves cleanly from left to right.
My job is to make the next handoff clearer
Working with agents has changed where I spend my time on software projects.
I spend more time defining the problem, checking assumptions, deciding which work can happen independently, and looking at what failed. I also spend time improving the systems that carry information between tasks, because a vague brief or a misleading failure report can waste the effort of every agent downstream.
I believe an agent should be able to explain what it changed and show the checks it ran before its work is treated as complete. If I can't see those things, I don't have enough information to decide what happens next.
The process will keep changing as I learn from it. For now, I'm watching whether better briefs and clearer failure handling make the next development push less dependent on someone untangling the queue afterward.